2026 07 Single Layer Rl
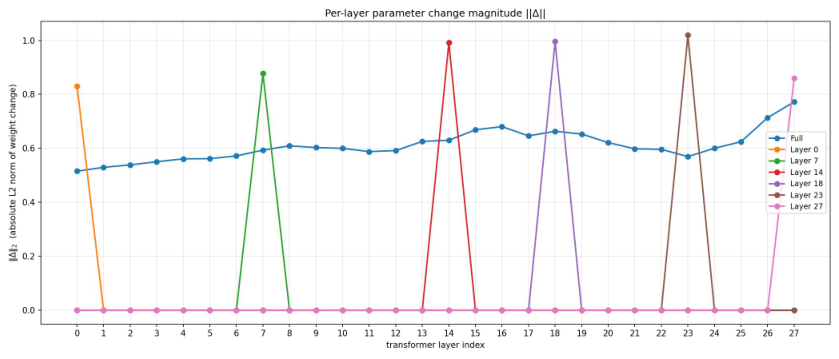
A new paper Is One Layer Enough? Training A Single Transformer Layer Can Match Full-Parameter RL Training, joint work with Zijian Zhang, Rizhen Hu, Athanasios, Dawei, Oscar and Hongzhou Lin, is available here. In this work, we study how the gains of RL post-training are distributed across the layers of a transformer, and find that training a single well-chosen layer – typically one in the middle of the network – recovers most of what full-parameter RL achieves.